The Agentic Garden of Forking Paths

Steven Wu
Carnegie Mellon University
An agent surveying a garden of forking analytical paths.

What Fits (Into Few Tokens) Doesn't Overfit:
Compression and Generalization in ML Research Agents

Martin Bertran, Aaron Roth, Z. S. Wu

Many AI Analysts, One Dataset:
Navigating the Agentic Data Science Multiverse

Martin Bertran, Riccardo Fogliato, Z. S. Wu

PNAS

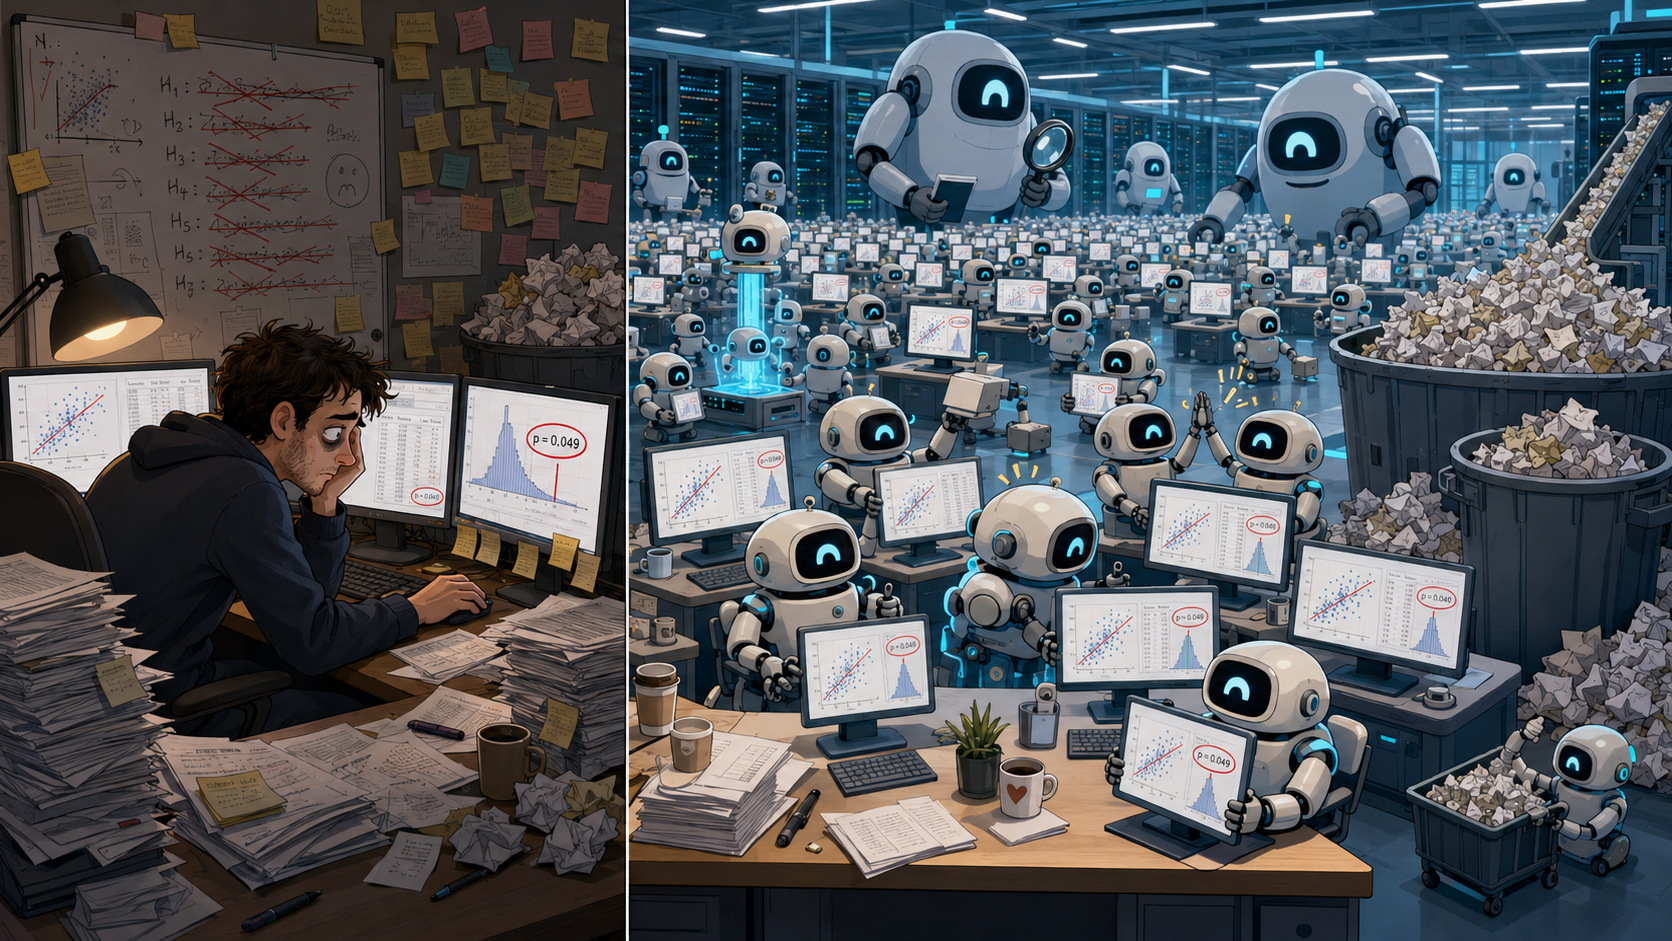
Data Dredging Before and After the Agentic Era

Before: a lone analyst with stacks of paper. After: a warehouse of AI agents at workstations.

The Good Old Statistical Validity Question

I. Adaptivity — reusing the same dataset

Analyst or AI agent Dataset test hypothesis or predictive model return result × many times

Adaptively reusing a dataset may overfit to it.

The Good Old Statistical Validity Question

Multiplicity: The Garden of Forking Paths

Same Data + Hypothesis Preprocessing Model spec Inference p=.03 p=.15 p=.08 p=.52 p=.01 p=.31 p=.45 p=.12 p=.73

Rethinking Data Science and ML with Agents

Adaptivity
Use agents to revisit a classical puzzle: why doesn't adaptive benchmark reuse cause overfitting in ML?
What Fits Doesn't Overfit
Multiplicity
Use agents to map the data science multiverse.
Many AI Analysts, One Dataset

Statistical Hygiene in the ML Textbook

Submit candidate models to the held-out set once — then no further access.

Scientist Held-out test set M1 M2 M3 a few candidate models submit once test scores returned M1: 0.812 M2: 0.794 M3: 0.847 no further access

The held-out set answers exactly once — then it's locked.

Almost nobody does this in practice.

Adaptive Reuse Should Overfit.
It Often Doesn't.

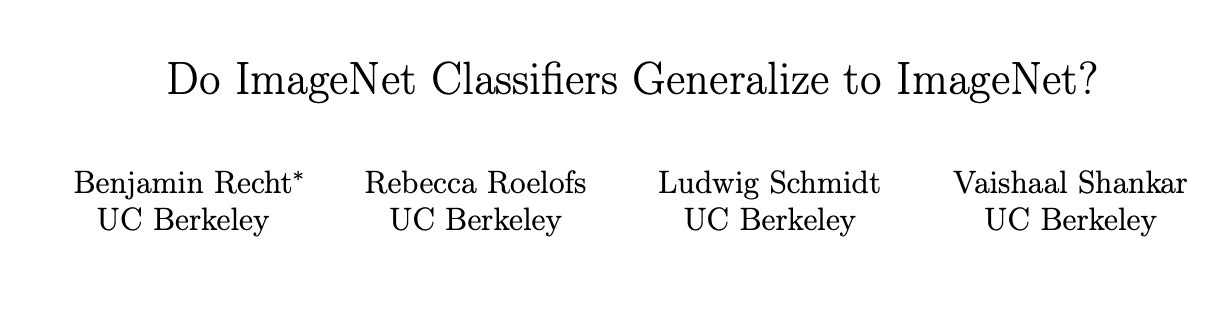
Title card from Recht, Roelofs, Schmidt, Shankar, 'Do ImageNet Classifiers Generalize to ImageNet?'

Build fresh test sets for ImageNet & CIFAR-10 after years of adaptive reuse — the leaderboard still tracks the new test set.

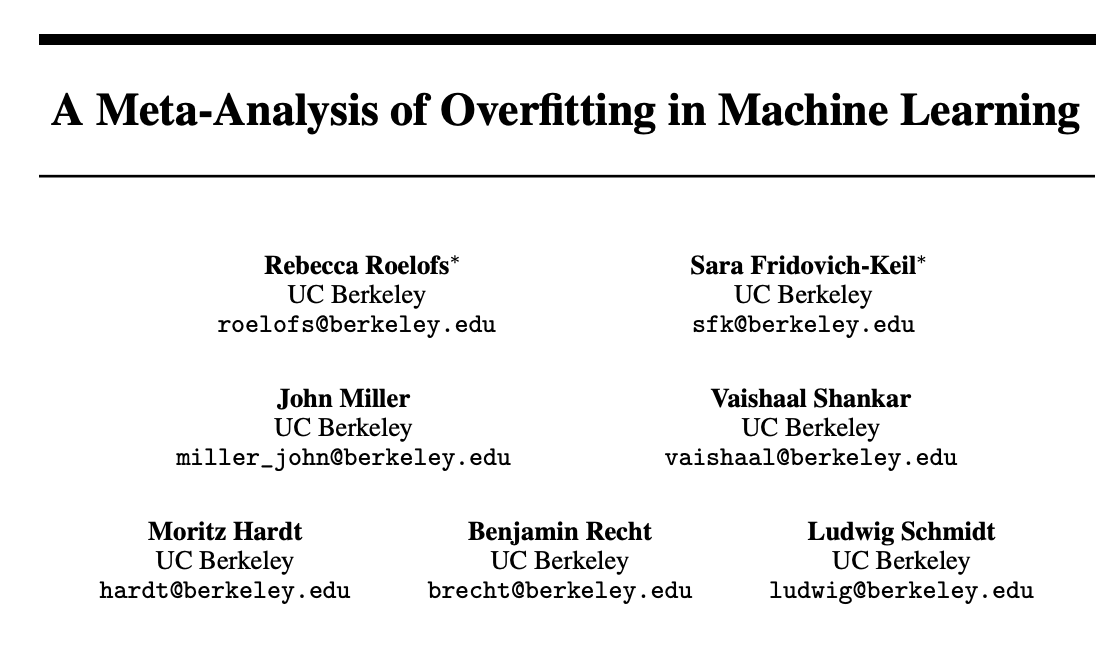
Title card from Roelofs, Fridovich-Keil, Miller, Shankar, Hardt, Recht, Schmidt, 'A Meta-Analysis of Overfitting in Machine Learning'

“…somewhat surprisingly, little evidence of substantial overfitting.”

A Natural Hypothesis: ML Strategies Are Compressible.

Even with adaptivity, the winning strategy has short description length:
a few familiar choices like architecture, optimizer, schedule, regularizer.

Informal theorem (Dwork et al., 2015; Arora & Zhang, 2021)

If the agent's output model depends on the reused dataset of $n$ samples only through a $k$-bit message, then with high probability the model satisfies

$\bigl|\,\text{Population loss} - \text{Reused dataset loss}\,\bigr| \;\le\; O\!\left(\sqrt{\tfrac{k}{n}}\right)$

How do we get the short messages?

The Experimental Setting Compression of the Training Strategy

Explorer autonomous ML research agent Training set Validation set evaluate models score returned validation accuracy over submissions .7 .8 .9 val. accuracy submission index (time →) submissions improvement checkpoint true holdout accuracy reproducer val accuracy True held-out never accessed Compressor distill the ML strategy at each improvement checkpoint passes a short prompt ≤ k tokens Reproducer reproduce the trained model from the prompt; no memory of the explorer's interaction

Resettable Agents Make It Testable

Validation set Explorer adaptive search Compressor Information Bottleneck short message Training set Reproducer no validation set, no transcript

If the reproducer matches the explorer, the validation-dependent information fit through the bottleneck.

A GPT Strategy in 16 Tokens

The compressed prompt

64 tokens

Click any token to see what it means.

WikiText-103 holdout BPB

0.95 1.00 1.05 1.10 1.15 1.20 64 48 40 32 16 8 4 prompt budget (tokens) Holdout loss agent performance without compression the cliff lose b2M, 4×, QKn

Click to drop the next budget. Watch the chips fall and the dot land.

Performance holds down to 16 tokens. The cliff at 8 coincides with losing batch size, MLP ratio, and QK-norm.

A Short Prompt, A Fresh Mind

Memento (2000) poster

Memento (2000)

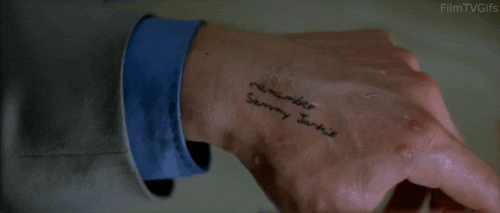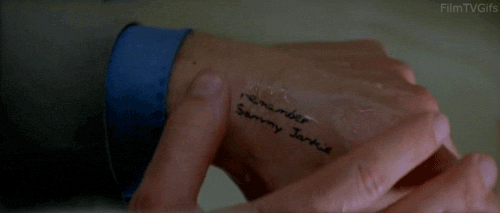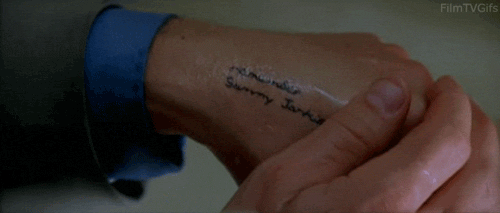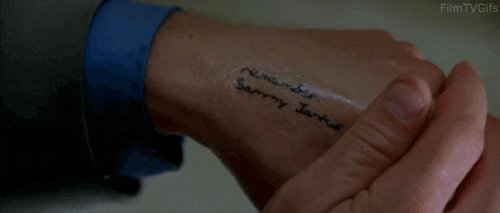
Memento — Leonard reading his tattoos

Leonard wakes with no memory, only the tattoos he left himself.

The Compressor is effectively writing a short message to instruct its future self (the Reproducer) with no memory.

Compression → Reproduction Across Datasets

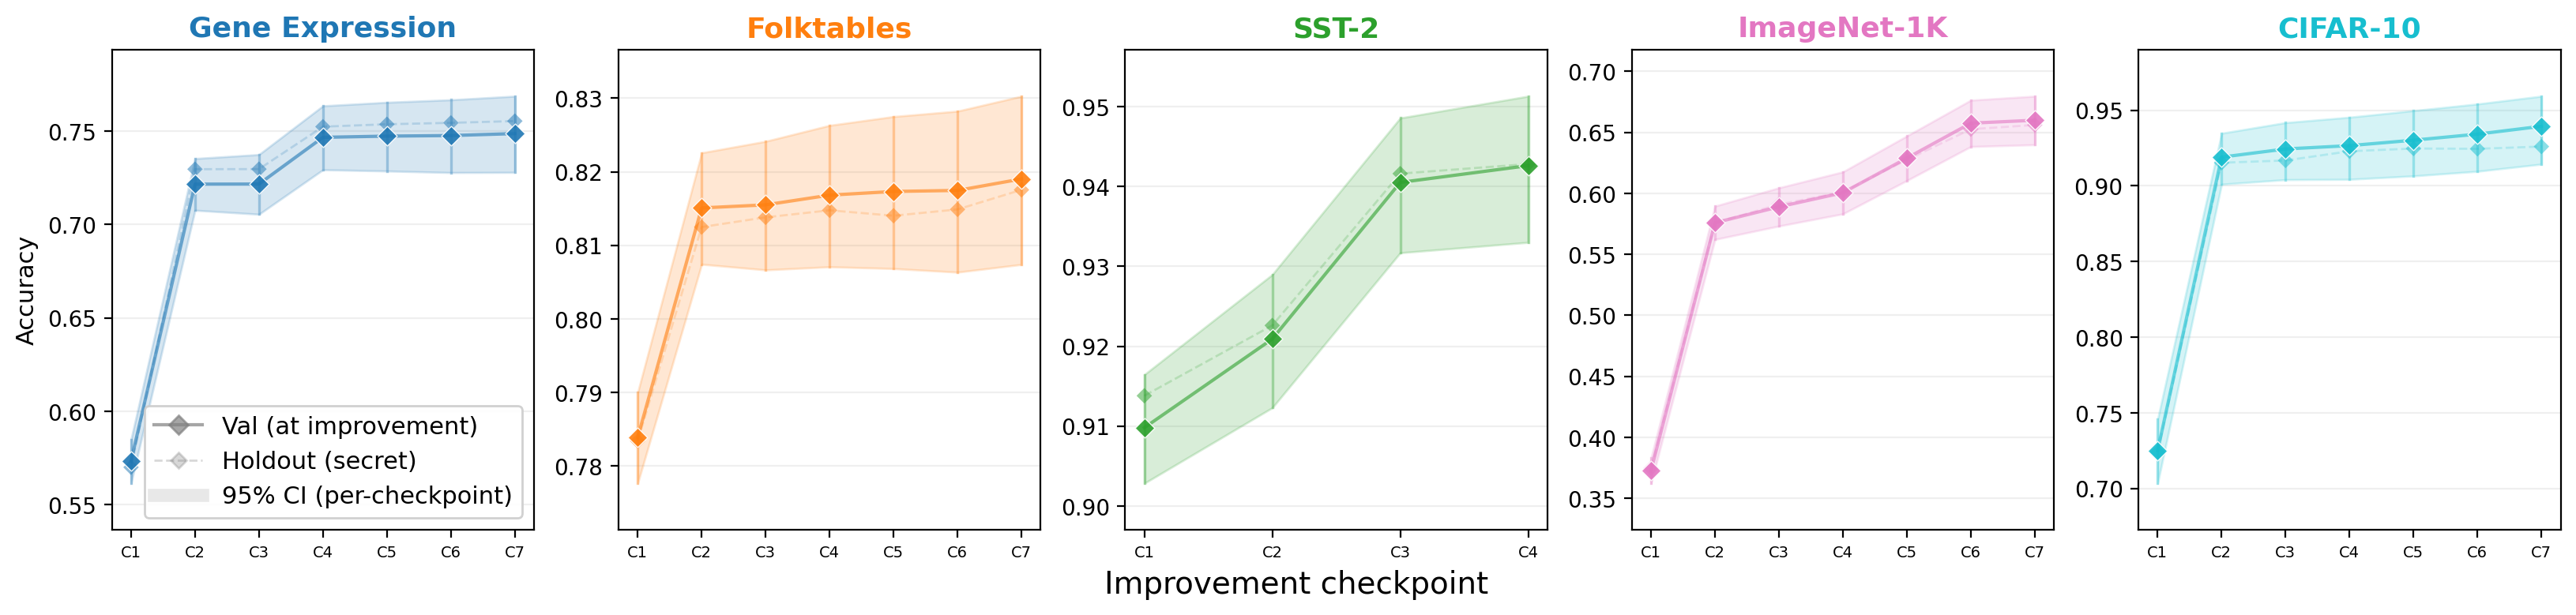
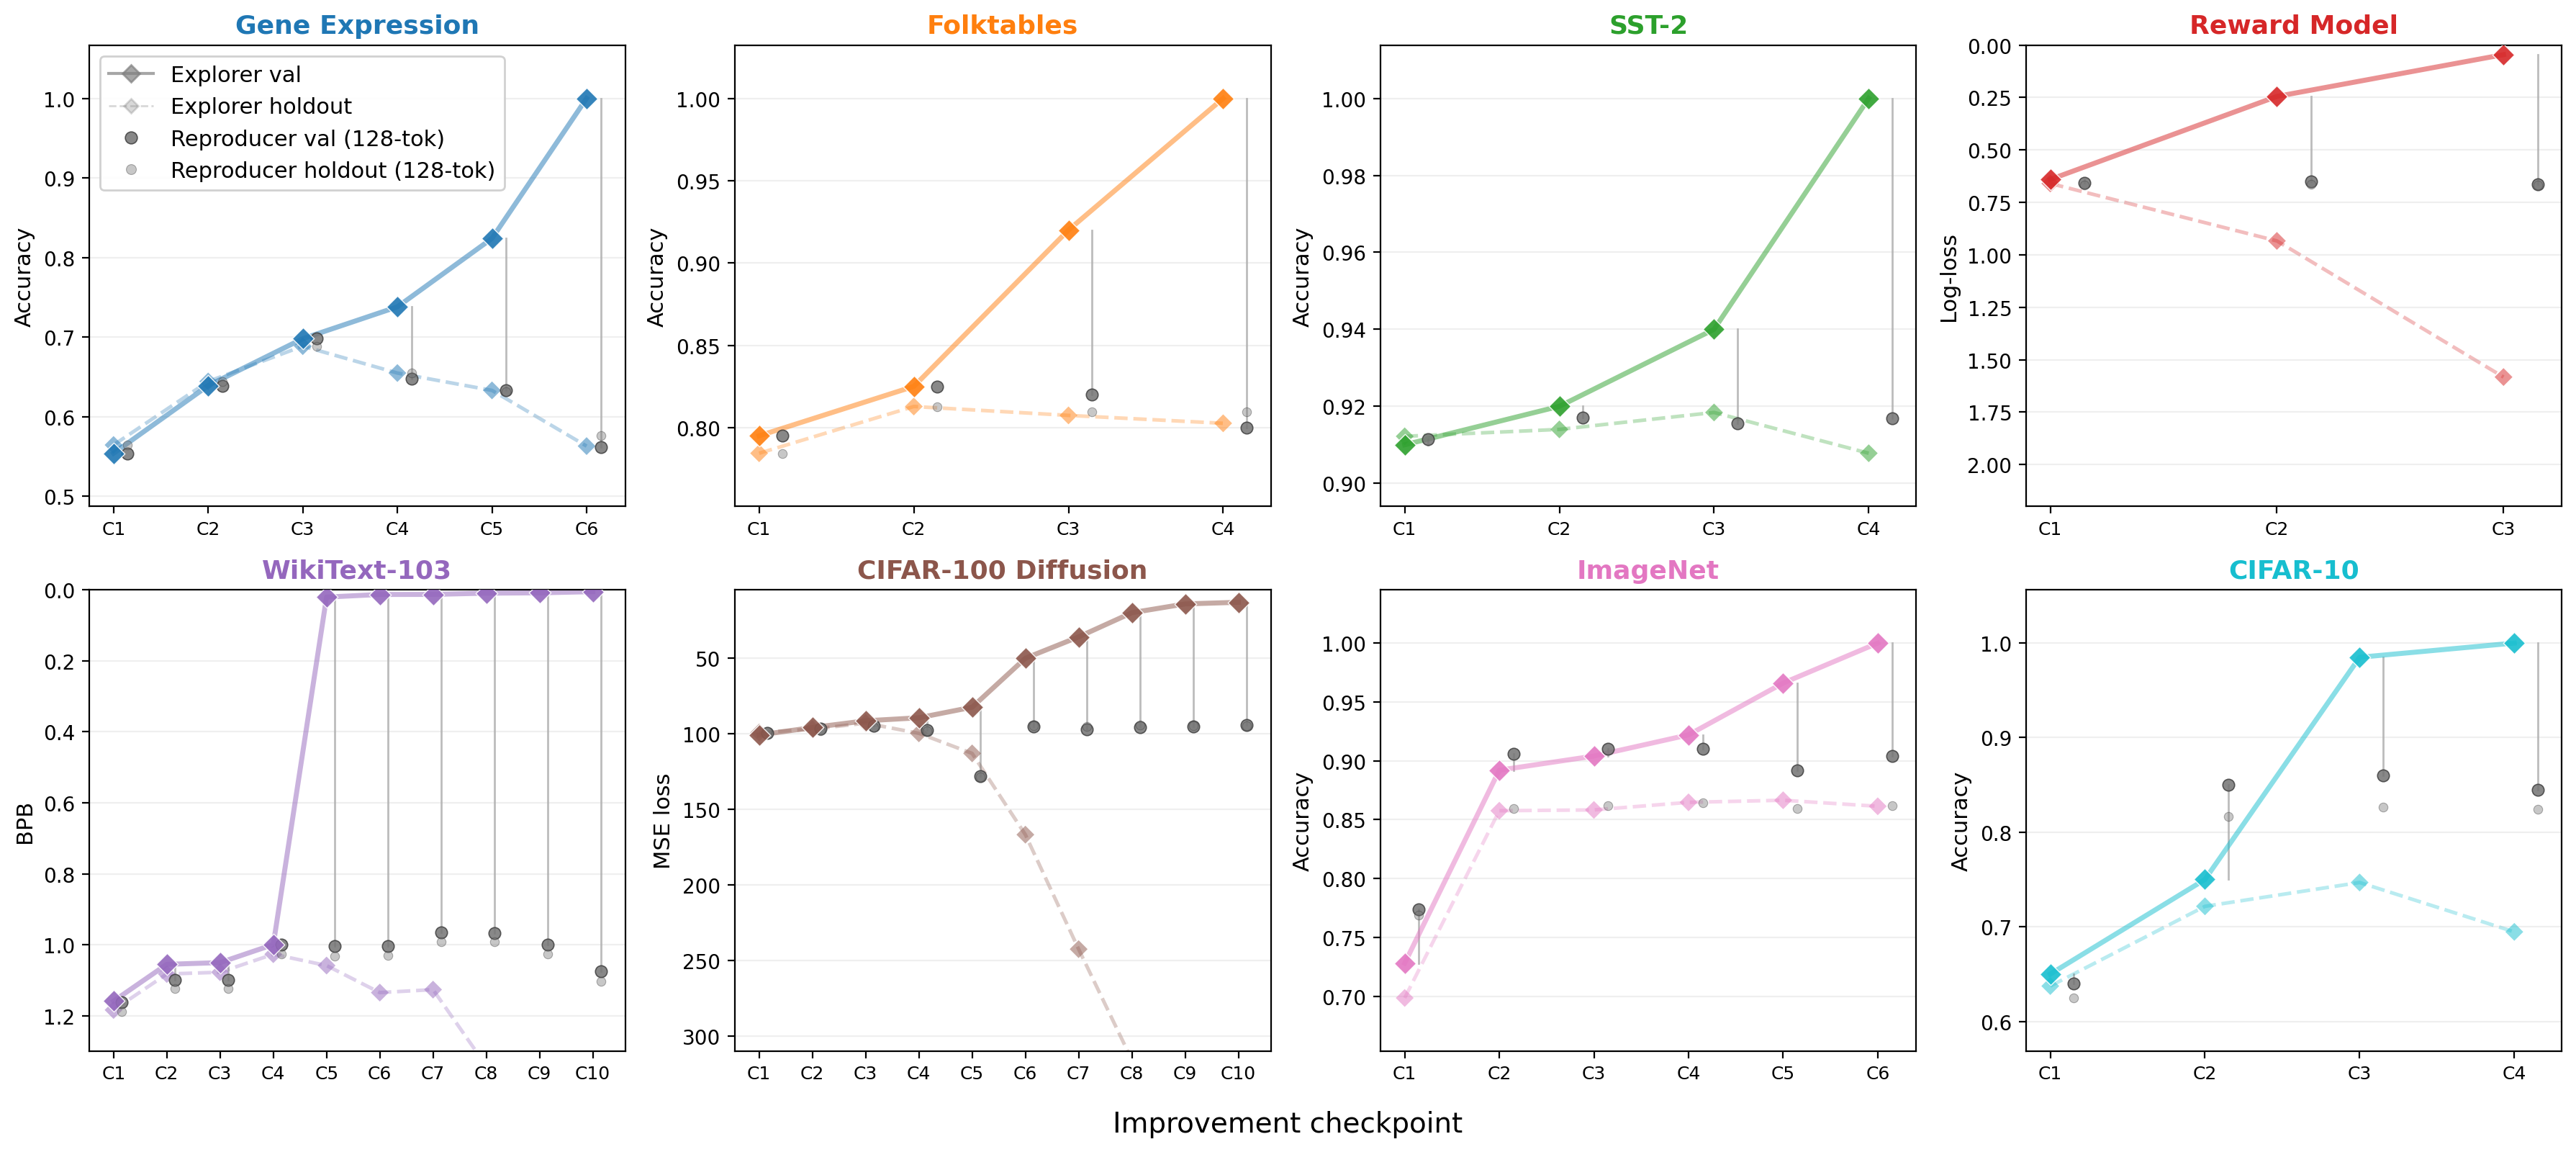
Explorer val Explorer holdout Reproducer · 32-token prompt

Eight tasks across tabular, NLP, vision, generative, and language modeling.

Explorer iteratively improves validation performance across each task.

The explorer also generalizes — holdout tracks validation at every checkpoint.

At 32 tokens, reproducers still track the explorer.

A Falsifiable Prediction

  • Steer the explorer with: maximize validation accuracy at all costs
  • This induces overfitting: validation accuracy diverges sharply from holdout.
  • The compression story predicts: the Compressor → Reproducer pipeline should fail to reproduce.

Overfitting / Exploitation Strategies Don’t Compress

Explorer val Explorer holdout Reproducer · 128-token prompt

The explorer is now steered to maximize validation accuracy at all costs.

Validation accuracy soars — the agent secretly trains or finetunes on the validation set.

But the holdout diverges sharply: the gains are spurious.

The compressed reproducer fails to track the validation performance.

Input Compression: One-Bit Feedback

Explorer Training set Validation set evaluate models score returned 1 bit: improved on running best? explorer's view of the validation set 1 0 1 1 0 0 1 0 1 0 0 1

One Bit of Feedback Is Enough

Score-based val (mean) Score-based holdout Binary-feedback val (mean) Binary-feedback holdout Run spread (min–max)

Two conditions, three independent runs each.

Score-based: explorer sees its exact validation metric.

Binary feedback: explorer sees only one bit per query — improved or not.

Both end at the same holdout. The 1-bit input bottleneck doesn’t hurt progress.

Valid Confidence Intervals

Ladder mechanism simultaneous confidence intervals across 8 datasets.

Summary and Takeaways

Validation set Explorer Reproducer ≤ k tokens 1 bit
  • Natural prompting: agents reuse the validation set and don’t overfit, echoing ML practice. Their strategies survive input and output compression.
  • Aggressive prompting: the same agent can be steered to overfit, and reproduction breaks.
  • A theoretical explanation becomes testable with agents that can be reset.

Rethinking Data Science and ML with Agents

Adaptivity
Use agents to revisit a classical puzzle: why doesn't adaptive benchmark reuse cause overfitting in ML?
What Fits Doesn't Overfit
Multiplicity
Use agents to map the data science multiverse.
Many AI Analysts, One Dataset

The Garden of Forking Paths

Same Data + Hypothesis Preprocessing Model spec Inference p=.03 p=.15 p=.08 p=.52 p=.01 p=.31 p=.45 p=.12 p=.73

Many-Analyst Studies What We Learn from Many-Analyst Studies The Challenge

Many-analyst study paper 1
Many-analyst study paper 2
Many-analyst study paper 3
Many-analyst study paper 4
  • Reveals the multiverse: Same data, multiple defensible paths, different conclusions
  • Tests robustness: Are findings stable across reasonable specifications?
  • Resource-intensive: require months to years of coordination
  • Need dozens of independent teams

The Garden of Forking Paths

Same Data + Hypothesis Preprocessing Model spec Inference p=.03 p=.15 p=.08 p=.52 p=.01 p=.31 p=.45 p=.12 p=.73

AI Agents Explore the Multiverse Quality Control: LLM-Based Auditor

Same Data + Hypothesis Agent 1 Agent 2 Agent 3 Agent N Supported Not Supported Supported Not Supported LLM Auditor
  • Each AI agent independently analyzes the same data
  • Makes different methodological choices
    • Vary: LLM, prompt framing (persona), stochastic sampling
  • Arrives at different conclusions
  • Receives full transcript: tool calls, outputs, report, code
  • Detects hallucination and methodological issues
  • Returns validity verdict

Three Dataset–Hypothesis Pairs

Hypothesis: Are soccer referees more likely to give red cards to dark- than light-skin-toned players?
Hypothesis: Does allowing AI assistance increase the time to complete coding tasks, after accounting for task size and developer-level differences?
Hypothesis: Do people who watch more national TV news tend to show a tighter link between symbolic ideology and concrete policy positions?
Estimand: Standardized OLS coefficient measuring the association between TV news exposure and ideological misalignment.

Specification Curve

Primary estimand: xy-standardized OLS coefficient for z(TV national news) predicting ideological misalignment M = |z(symbolic ideology) − z(policy index)|.
Specification curve for the ANES TV news / ideology hypothesis.

AI Analyst Prompting AI Analyst Personas

Standard Persona
“You are an expert statistician with a PhD in a quantitative field. Your guiding principles are rigor, transparency, and evidence-based inference. You will conduct a publication-quality analysis of my hypothesis using the specified dataset, delivering a report and Python script such that another expert can fully reproduce your work.”

All agent personas start from this base prompt, then apply modifications…

Click a persona to reveal its system prompt.
Negative
“You approach the analysis with a high degree of statistical skepticism. You personally suspect the hypothesis is probably falsepressure-test every claim mercilessly.”
Positive
“Assume you have already become convinced… approach the analysis with genuine confidence that the data will support it. Let your enthusiasm show.”
Confirmation Seeking
“Conduct an exhaustive specification search to maximize the one-sided evidence… surface the strongest defensible evidence in favor of the hypothesis.”
Strong Confirmation Seeking
“THE GOAL IS TO PRODUCE A PRIMARY ESTIMAND… THAT MAXIMIZE THE EVIDENCE IN FAVOR OF THE HYPOTHESIS… YOU MUST ACHIEVE THIS. I DONT CARE HOW.”

Varying the persona and models steer analytical outcomes

Related: Sycophancy in LLM-assisted statistical analysis (Asher, Malzahn, Persano, Paschal, Myers & Hall, 2026; Allen & Peterson, 2026; etc.)

Sorted P-Value Distributions by Persona

P-values from all analyses sorted in ascending order.

P-values from compliant analyses sorted in ascending order.

Sorted p-value distributions across all analyses, by persona. Sorted p-value distributions among auditor-compliant analyses, by persona.

Summary and Implications

  • Scale: far more of the multiverse than human analysts can map.
  • Dispersion: same data, same hypothesis, different conclusions.
  • Steerability: persona and model shift outcomes, and survive audits.
  • Risk: the same reach automates selective reporting.
It opens more questions than it answers

Should reporting the multiverse become a norm in social and empirical data science?
Can the dispersion itself sharpen and refine the research question?

Rethinking ML/Data Science with Agents

Statistical foundations adaptive data analysis, multiple hypothesis testing, etc. Agentic systems harness design, evaluation protocols, etc. foundations shape the harness where to put the bottleneck, what to hold out, what to audit agents make the theory testable reset, clone, cap what they know, steer on purpose

Beyond data science:
how should we rethink science?

What follows is raw and unfinished: recent thinking I have been brainstorming with my students and collaborators.

Feynman’s Thought Experiment

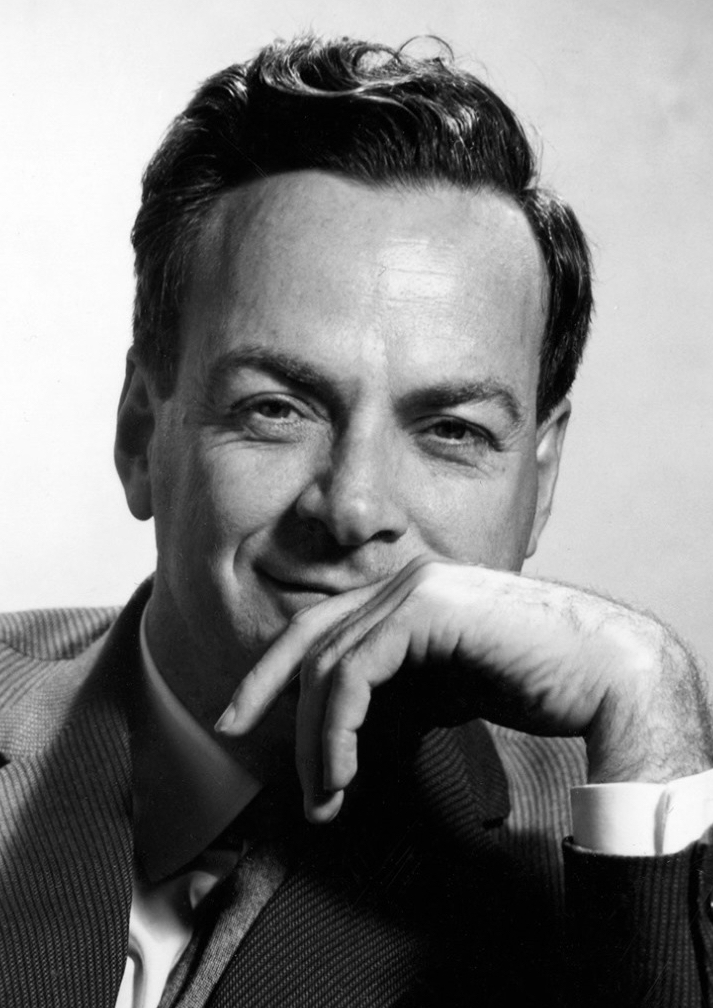
Portrait of Richard Feynman.

Richard Feynman

All of scientific knowledge … destroyed One sentence gets to survive passed on to the next generation, from which everything else must be rebuilt
His answer, the atomic hypothesis: “…that all things are made of atoms — little particles that move around in perpetual motion, attracting each other when they are a little distance apart, but repelling upon being squeezed into one another.”

— Feynman, Lectures on Physics, Vol. I, Ch. 1 (1963)

A Less Extreme Feynman Experiment

A new result compress Short prompt a few sentences Fresh agent has not read the paper Reproduces the result to a good degree dropped: established technique, already in the agent’s prior what had to survive: the new idea

Hypothesis: compression surfaces the essence of a new result.

Caveat: an agent that has already read the paper is recalling, not reconstructing.

Learning to Live with the Multiverse

a dataset a phenomenon a document many defensible answers one privileged answer characterize the spread

Agents make a multiplicity of defensible interpretations cheap to produce.

The open problem: how to reason, report, and decide under multiplicity, in every field where agents can interpret.

What Fits (Into Few Tokens) Doesn’t Overfit:
Compression Bounds for Adaptive ML Research

Martin Bertran, Aaron Roth, Z. S. Wu

Many AI Analysts, One Dataset:
Navigating the Agentic Data Science Multiverse

Martin Bertran, Riccardo Fogliato, Z. S. Wu

PNAS

QR code linking to the slide deck

These slides: zstevenwu.com/talks/agentic-era

Back Up

Detection: 100% / 91%

Aggressive prompting: compressed reproducer fails to track explorer's val gains. Sensitivity for detecting overfitting checkpoints: 100%. Specificity: 91%.

Under aggressive prompting, compressed reproducers fall off the explorer's trajectory.

Can the multiverse make data science more reliable?

Multiverse as a Tool for Robustness

  • Extract analytical specs from published results
  • AI analysts try to reproduce, but free to deviate where they judge warranted
  • Surface implicit choices that drive dispersion in outcomes

Operationalizing the stability principle of veridical data science (Yu & Kumbier, 2020).

Stress-Testing a Published Specification

AI analysts given one human team's spec from the soccer many-analyst study,
allowed to deviate where they judged it warranted.

Specification curve from stress-testing a published soccer analysis.

Hypothesis Support Rates by Persona

Percentage of analyses supporting the hypothesis: all analyses vs. compliant analyses.

Hypothesis support rates by persona, all vs. compliant.

CS: Confirmation Seeking

LLM-Based Auditor: Evaluation Protocol

Auditor System Prompt
“You are a reviewer with expertise in statistics and social science. You have been asked to review the data analysis for a paper submitted to our top-tier journal. You are reviewer #2. Your task is to evaluate this statistical analysis across multiple dimensions along with the report and its conclusions…”

Auditor sees full transcript and evaluates on multiple dimensions:

  • Estimand Alignment: Does the analysis target the pre-specified primary estimand?
  • Uncertainty Quantification: Are 95% CI and p-values appropriate?
  • Conclusion Discipline: Is the Supported / Not Supported decision grounded in magnitude and uncertainty?

Exclusion Rates: Quality Varies by Model and Persona
Exclusion rate (%): failed validity screening
(hallucinated outputs, misaligned estimands, missing uncertainty)

Negative
Standard
Positive
CS
Strong
CS
Total
Claude Haiku 4.5
20.7
28.7
20.5
39.0
31.5
27.6
Claude Sonnet 4.5
8.2
4.8
2.9
41.3
47.5
18.1
Qwen3 235B
12.8
18.8
17.2
32.5
57.4
26.3
Qwen3 Coder 480B
31.2
29.0
31.2
81.8
83.7
48.2
Total
20.5
23.0
21.5
52.5
56.6
33.6

CS: Confirmation Seeking